Hello There!

Lorem ipsum dolor sit amet, consectetur adipiscing elit,

 About tatvic

Tatvic, a Google Premier Partner, empowers industry leaders with end-to-end Data & Marketing Analytics, leveraging Cloud, Analytics, Maps, and AI/ML for data-driven insights and future-proof digital growth.

Linear Regression using R

Regression

Through this post I am going to explain How Linear Regression works? Let us start with what is regression and how it works? Regression is widely used for prediction and forecasting in field of machine learning. Focus of regression is on the relationship between dependent and one or more independent variables. The “dependent variable” represents the output or effect, or is tested to see if it is the effect. The “independent variables” represent the inputs or causes, or are tested to see if they are the cause. Regression analysis helps to understand how the value of the dependent variable changes when any one of the independent variables is varied, while the other independent variables are kept unchanged. In the regression, dependent variable is estimated as function of independent variables which is called regression function. Regression model involves following variables.

  • Independent variables X.
  • Dependent variable Y
  • Unknown parameter θ

In the regression model Y is function of (X,θ). There are many techniques for regression analysis, but here we will consider linear regression.

Linear regression

In the Linear regression, dependent variable(Y) is the linear combination of the independent variables(X). Here regression function is known as hypothesis which is defined as below.

hθ(X) = f(X,θ)

Suppose we have only one independent variable(x), then our hypothesis is defined as below.
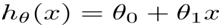
The goal is to find some values of θ(known as coefficients), so we can minimize the difference between real and predicted values of dependent variable(y). If we take the values of all θ are zeros, then our predicted value will be zero. Cost function is used as measurement factor of linear regression model and it calculates average  squared error for m observations. Cost function is denoted by J(θ) and defined as below.

As we can see from the above formula, if cost is large then, predicted value is far from the real value and if cost is small then, predicted value is nearer to real value. Therefor, we have to minimize cost to meet more accurate prediction.

Linear regression in R

R is language and environment for statistical computing. R has powerful and comprehensive features for fitting regression models. We will discuss about how linear regression works in R. In R, basic function for fitting linear model is lm(). The format is

fit <- lm(formula, data)

where formula describes model(in our case linear model) and data describes which data are used to fit model. The resulting object(fit in this case) is a list that contains information about the fitted model. The formula typically written as

Y ~ x1 + x2 + … + xk

where ~ separates the dependent variable(y) on the left from independent variables(x1, x2, ….. , xk) from right, and the independent variables are separated by + signs. let’s see simple regression example(example is from book R in action). We have the dataset women which contains height and weight for a set of 15 women ages 30 to 39. we want to predict weight from height. R code to fit this model is as below.

>fit <-lm(weight ~ height, data=women)
>summary(fit)

Output of the summary function gives information about the object fit. Output is as below

Call:
lm(formula = weight ~ height, data = women)

Residuals:
    Min      1Q  Median      3Q     Max
-1.7333 -1.1333 -0.3833  0.7417  3.1167 

Coefficients:
             Estimate Std. Error t value Pr(>|t|)
(Intercept) -87.51667    5.93694  -14.74 1.71e-09 ***
height        3.45000    0.09114   37.85 1.09e-14 ***
---
Signif. codes:  0 ‘***’ 0.001 ‘**’ 0.01 ‘*’ 0.05 ‘.’ 0.1 ‘ ’ 1 

Residual standard error: 1.525 on 13 degrees of freedom
Multiple R-squared: 0.991,	Adjusted R-squared: 0.9903
F-statistic:  1433 on 1 and 13 DF,  p-value: 1.091e-14

Let’s understand the output. Values of coefficients(θs) are -87.51667 and 3.45000, hence prediction equation for model is as below

Weight = -87.52 + 3.45*height

In the output, residual standard error is cost which is 1.525. Now, we will look at real values of weight of 15 women first and then will look at predicted values. Actual values of weight of 15 women  are as below

>women$weight
Output
[1] 115 117 120 123 126 129 132 135 139 142 146 150 154 159 164

Predicted values of 15 women are as below

>fitted(fit)
Output
       1        2        3        4        5        6        7        8        9
112.5833 116.0333 119.4833 122.9333 126.3833 129.8333 133.2833 136.7333 140.1833
      10       11       12       13       14       15
143.6333 147.0833 150.5333 153.9833 157.4333 160.8833

We can see that predicted values are nearer to the actual values.Finally, we understand what is regression, how it works and regression in R.

Caveat

Here, I want to beware you from the misunderstanding about correlation and causation. In the regression, dependent variable is correlated with the independent variable. This means, as the value of the independent variable changes, value of the dependent variable also changes. But, this does not mean that independent variable cause to change the value of dependent variable. Causation implies correlation , but reverse is not true. For example, smoking causes the lung cancer and smoking is correlated with alcoholism.  Many discussions are there on this topic. if we go deep into than one blog is not enough to explain this.But, we will keep in mind that we will consider correlation between dependent variable and independent variable in  regression.

In the next blog, I will discuss about the real world business problem and how to use regression into it.

Would you like to understand the value of predictive analysis when applied on web analytics data to help improve your understanding relationship between different variables? We think you may like to watch our Webinar - How to perform predictive analysis on your web analytics tool data. Watch the Replay now!

Regression with Google Prediction API

Prediction API

Welcome to the last part. In the previous blog, we have discussed about the model improvement and seen the summary of the improved model. In this post, I will discuss about regression with Google prediction API, compare it with our regression model and predict the bounce rate. When I used Google prediction API on the our data set, I found  following  result.


Let’s understand result first. Id of the model is “a1”, model type is “REGRESSSION”, number of instances are 8488(i.e. data set contains 8488 rows) and most important result is mean squared error which is 704.82. Here, there is no information about the coefficients of the model. Then, question arise how to evaluate model? Don’t worry, I will explain.

In the first part, I have explained about cost and if the cost is minimum then model is better. Cost of Google prediction API result is calculated as the square root of the mean square error and it is 26.55. However the cost of our improved model is termed as residual standard error and it is 24.83. If we compare these two costs , then we can say that R regression model is similar to the Google prediction API model.

After understanding the relationships between the bounce rate and time components, let’s predict the bounce rate through regression model. R provides predict() function to generate prediction. Suppose we have following observation for a webpage

  • avgServerResponseTime - 0.427189189
  • avgServerConnectionTime - 0.007081081
  • avgRedirectionTime - 0.318081081
  • avgPageDownloadTime - 0.416432432
  • avgDomainLookupTime - 0.033351351
  • avgPageLoadTime - 3.395026316

R code to generate prediction is as follow.

>insert_frame<- data.frame(avgServerResponseTime=0.427189189,avgServerConnectionTime=0.007081081,avgRedirectionTime=0.318081081,avgPageDownloadTime=0.416432432,avgDomainLookupTime=0.033351351,avgPageLoadTime=3.395026316)
>predict(Model_2,insert_frame,type='response')
Output
50.14

Let’s check the prediction of the above observation with Google Prediction API. This is shown below.

From the above result, we can see that prediction for observation is 48.39 and it is similar to the our prediction model.

Would you like to understand the value of predictive analysis when applied on web analytics data to help improve your understanding relationship between different variables? We think you may like to watch our Webinar - How to perform predictive analysis on your web analytics tool data. Watch the Replay now!

Visitor analysis using Google Analytics-Visitors Flow

“Flow Visualization” in Google Analytics is a tool that allows you to analyze site insights graphically, and instantly understand how visitors flow across pages on your site. Currently GA offers two  types of visualizers: “Visitors Flow” and “Goal Flow” .The Visitor Flow Report allows you to graphically see the visitor’s navigation through your site. It shows exactly where the users came from, and which page they entered, progressed to, and left from. It is located under the grouping of Audience reports (the last option).
For this blog post,  my focus would be on how you can get better visitor insights using Visitors Flow. We will quickly traverse through three cases that can help you gain in-depth insight on your visitors.

How would Visitor flow report help me?

You can view the navigation from almost any dimension, such as country, source, medium, campaign and more. You can further slice it with advanced segments. Let’s take few cases that could help you know your visitors well.

1.    Analyze most popular path:
You can analyze the most popular path visitors take. Use this to plan and path your goal which will help you analyze how converting and non-converting users navigate your site. What after this? Well, this will help you making many decisions like:  Once you know the most popular path, you can decide the most strategic page (one amongst the most popular path’s pages) for particular advertisement or any content important to visitor’s conversion.

2.     Analyze the difference between paths of converting and non-converting visitors:
By analyzing the difference between the path of converting and non-converting visitors, you can gain many insights about what works best. For example, if the visitor A follows path (a->b->c->D) and converts (page D being the conversion page) and on the other hand visitor B follows the path (x->b->z->D) and does not convert , then there could be an issue with pages-x,z or may be the sequence is not working with them. But, this can be concluded if there are quite a few visitors that depict this behavior.

3.    Analyze your new visitors:
If your site experiences sudden boom in traffic you can analyze the properties of the new visitors, for example, country, and traffic source like campaign. You can also choose to include all visitors (instead of new visitors) to get the generalized idea of all the visitors.

Geographic Location specific Visitor Flow

4.    Analyze the properties of frequently converting visitors:

Language specific Visitor Flow

Looking at the country of visitors who convert (visits with transaction), say visitors from Brazil. If there are around 2k visitors who convert but, your site is only in US-English. Considering the number of people converting and the potential of further conversion rate from Brazil you may consider offering your site content in Portugal language as well. This will help you increase you conversions. Although, this is doable using custom reports, but the visual appeal and also the path followed by the visitors is an add on here which can help you gain better insights.
Campaign specific Visitor Flow

There is much more to this, you can apply various advanced segments, metrics and dimensions to narrow down your results and gain focused and helpful insights. But, to begin with, I hope this would be helpful.

Bot Icon
Bot Icon

Tatvic Bot

Explore About Tatvic and Services